
Scalability
3 articles
Choosing an LLM Inference Architecture: How the Latency–Cost–Scalability Trilemma Shapes Your Deployment
LLM inference faces a trilemma: balancing latency, cost, and scalability. This article explores dedicated GPU clusters versus managed serverless endpoints to help you choose the optimal architecture for your application's needs.
Solving the Quantum Wiring Problem: How Cryo-CMOS Unlocks Scalable Processors
Cryogenic CMOS (cryo-CMOS) circuits are emerging as a critical technology for scaling quantum computers by enabling control electronics to operate at ultra-low temperatures. This integration directly addresses the wiring, power, and complexity bottlenecks that have limited the growth of quantum processors.
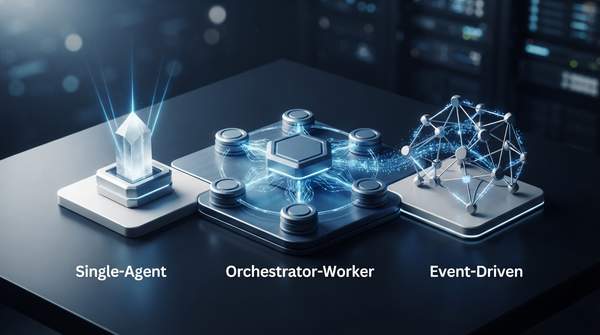
Comparing AI Agent Architectural Patterns for SaaS Platforms
Integrating AI agents into SaaS platforms requires careful architectural decisions. This article compares key patterns like Single-Agent, Orchestrator-Worker, and Event-Driven architectures, detailing their trade-offs for scalability, complexity, and performance to guide your selection.